
sreyansjain
Can someone please give me an example of an application where erlang term_to_binary and binary_to_term have been used for state management using OTP instead of a database.
Generally the way I (and maybe most others) have been modelling applications is by thinking in terms of database tables and their relationships. This has been going on for long and is often easier than thinking probably in DDD terms, especially for junior developers. They way hardware prices have come down I think many applications (not internet scale) can easily fit their data in the RAM. So it would be great if someone can advise me how to use OTP and files for state management of smaller applications.
Also I think its very difficult to rule out the utility of a database (mainly POSTGRES) because of the reporting requirements. Should we go for the file based approach how do we tackle this?
I am more confused by reading Doing without database in the 21st century.
Would going the databaseless route won’t be very hard? ACID etc.
If someone can shed some light on this it would be really enlightening and helpful.
Thanks
Where Next?

Trending in Questions



Other Trending Topics


Latest on Elixir Forum
Sponsor Spotlight

Master modern tools, write cleaner code, and tackle real-world challenges with Manning books, videos, and courses. Start building today.
Categories:
Sub Categories:
Forums
Popular Tags
- #ecto
- #liveview
- #troubleshooting
- #learning-elixir
- #library
- #deployment
- #erlang
- #testing
- #genserver
- #mix
- #absinthe
- #remote-other
- #otp
- #plug
- #how-to-question
- #macros
- #postgres
- #elixirconf
- #channels
- #exunit
- #discussion
- #code-sync
- #podcasts
- #javascript
- #onsite
- #dialyzer
- #docker
- #authentication
- #umbrella
- #full-time-contract
- #podcasts-by-brainlid
- #ecto-query
- #ai
- #elixirconf-us
- #blog-post
- #elixir-ls
- #phoenix_html
- #iex
- #graphql
- #genstage
- #websockets
- #supervisor
- #advent-of-code
- #distillery
- #processes
- #api
- #forms
- #elixirconf-eu
- #metaprogramming
- #hex
Our Sponsors

Build Elixir applications with speed and confidence.

Supporting innovation across the BEAM ecosystem.

We build reliable cloud platforms for business-critical systems.

Error tracking, logs, uptime, and Just Enough APM. Built for developers.

Elixir, Erlang & BEAM conferences from Code Sync - join us in 2026!

Practical resources that improve the lives of professional developers.
Master modern tools, write cleaner code, and tackle real-world challenges.

Producing high quality Elixir screencasts since 2017.

The team behind Membrane, Popcorn, LiveDebugger. Available for hire.

Courses that'll move you from confusion to "Aha, now I get it!"
Showing Posts 1 to 10- Show Best Posts
- Show All (oldest first)
- Show All (newest first)
tomekowal
Everything depends on the use case.
I am pretty sure you have some concrete examples in mind while asking. It might be useful to share your particular scenario.
In this book Functional Web Development with Elixir, OTP, and Phoenix author shows how to make an interactive game. When the game is ready and works in memory, he adds saving state in ETS in case of crashes and mentions that it could use dets (disk based term storage).
He does exactly the thing you describe as confusing: starts without touching the DB and ends up with an excellent model decoupled from storage. I highly encourage reading it!
[EDIT] I would also treat Why Relational Databases Are So Bad with a grain of salt. The timesheet example might ring a bell in people. Adding sequence ids to rows in data and work to produce a report from SQL is repetitive. The same goes with retrieving employee name from a different table.
What the author doesn’t mention is that storing employees and hours separtely and normalising the database allows to easily reverse the query: “who worked at a given time?” Try that with saving timesheets as a list of hours in a file
Again: everything depends on the use case. Maybe you will never need that reversed query?
hpopp
I recently tried this approach building a new production service. It managed lists of contacts with some additional business logic, each list getting its own GenServer with state backed up to S3. Each GenServer would gracefully shut down after a few minutes of inactivity to avoid memory leaks. In short, we scrapped the whole thing and reimplemented with postgres.
Building without a database allows you to write some of the most expressive code you’ll ever create, at the expense of having to write a lot of things you take for granted in traditional design.
Big issues I faced:
term_to_binary, but obviously this gets hairy if data needs to change. Lacking the time to implement a proper migration strategy due to deadlines, I ultimately decided to abandon the whole approach.It’s entirely possible I implemented it wrong, and I do intend to try it again in the future. Ultimately I felt like the system I had built wasn’t nearly as stable or simple as a database, and given the scheduling deadlines, stability and simplicity had to come first.
As a side note, the original business requirements had us under the impression that contact lists would be no greater than 10K entries. We had a 45K list day one in production, with the expectation to have multiple 100K+ lists in the coming weeks.
idi527
I tried a similar approach last summer, but with sqlites stored on google storage. Each user had an sqlite database. And I also switched back to Postgres since the ecto adapter for sqlite wasn’t quite as nice to work with as the one for Postgres. I also worried a bit about race conditions, where two clients would start at the same time and both download and start writing to the same database.
I mostly did that to try out hosting the application entirely on preemtible/spot instances in the cloud.
dimitarvp
The no-DB approach sounds awesome when you’re building exercise apps but unless you need barely any reporting or joining of data, then it doesn’t scale beyond the first two weeks of active development.
The problem is never “what is the exact way my app is persisting information?”. The problem always has been “how do I query and aggregate it?”.
IMO the way relational DBs build indices and joins – and the internal storage mechanism in general, including transactions – needs to be ported to an embedded DB. People around here periodically attempt to write apps using only (D)ETS as a storage and the conclusion always seems to be “it’s too hard to arbitrarily query data”.
If I had the time and was paid for it I’d seriously attempt writing such an embedded DB engine.
…Or, it might be worth it to contribute to the sqlite Elixir adapter. But then again, sqlite only allows a single write operation at a time.
idi527
I know you didn’t reply to me, but let me leave some notes on how I’d handle some of this:
I planned to use some ad-hoc approach (and later switch to spark) to build materialised views. I never got to do it, but I don’t see much reason why it wouldn’t work.
With WAL enabled, so as not to block reads, it’s enough if used carefully. For example, since in my setup all users had their own databases (colocated with the user processes at execution time), all requests took less than 1ms (but it could eventually get worse as more users → more databases → more files → more filesystem thrashing, there’s a way around it with storing multiple sqlite databases in a single lmdb, but I never really looked into it), whereas after switching to Postgres it was about ~30ms. The app was a simple voice messaging app, so the requests were “do I have new messages?”, “get message history with X”, “send message to Y”, “get prekeys for convo with Z”.
benwilson512
IMHO If the purpose of the application is to store and manage data, then you can either use a database or build a database, and you probably don’t want to build a database.
However, there are applications who have jobs that isn’t storing and managing data. For example, we have applications which route data and others that serve as kiosk systems. For these, a database was superfluous. Just my $0.02.
keathley
This is exactly right. Unless your company sells a database don’t build a database.
To add on to this, I don’t know of many companies that don’t need to store something. My advice is to put your state into a reliable database (postgres is a good default). As other people have said this empowers reporting, etl, and a whole bunch of other benefits.
It’s not the only reason, but the main reason to build stateful systems - meaning bringing your application’s state into processes - is to reduce latency. I have a lot of empirical evidence to support that a “stateless” elixir service backed by a database will take you a really long way. IMO you need to prove that postgres or your db of choice won’t be fast enough before you start bringing more state into your application.
peerreynders
Unless your company develops databases, the database probably isn’t your application. That’s the basis of opinion pieces like No DB:
i.e. relational databases can be very useful but their existence shouldn’t dominate the architecture - possibly to the point where the UI is assembling dynamic SQL.
And in some circumstances other approaches to managing/handling data can be more effective:
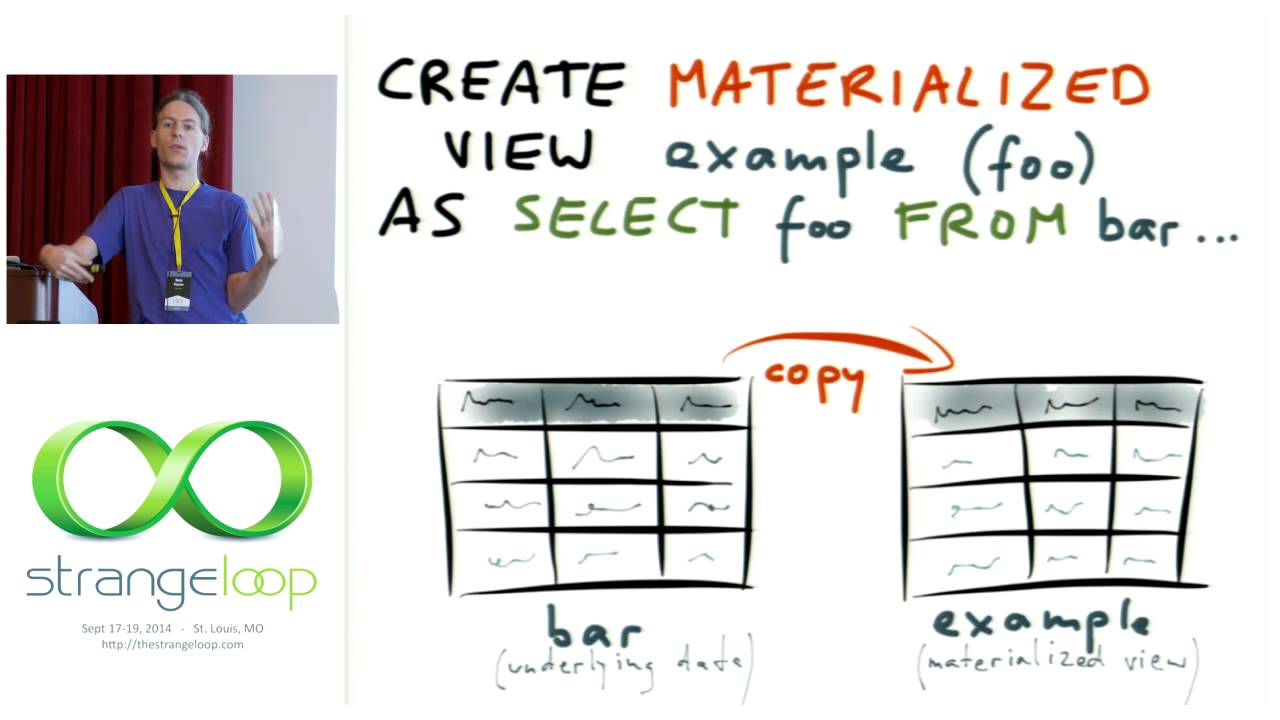
“Turning the database inside out with Apache Samza” by Martin Kleppmann
keathley
I’ve worked on multiple systems that democratized their data through kafka and other mechanisms. Based on those anecdotes I’m more then comfortable suggesting that most companies should not do this.
All that aside, most companies are information systems. Meaning they take data, store data, and present that data to users as information. That being the case the database absolutely does matter. Its not “just a detail”. Its an integral part of your business and you should choose databases that have the tradeoffs your business needs.
peerreynders
The message is that your core problem should dictate which data handling technology is appropriate.
Before the emergence of NewSQL and stream processing it wasn’t uncommon for “the” relational database to be the foundation and crown jewel of the all business processing - the core of a brittle and tightly coupled BBoM. Unfortunately technology centric design can happen all too easily with any technology.