
Fl4m3Ph03n1x
Background
I have an Elixir application that has 2 machines. Each machine receives requests on a round robin base.
Both machines are connected to a single Redis instance, which works as a global cache.
If machine A receives a request, it caches the request/response in Redis. Should machine B get the same request, it won’t need to re-calculate the answer.
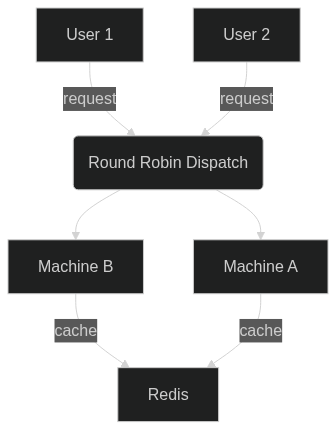
Questions
I know that ETS is usually used for caching.
However this cache is local to machine A and local to machine B.
My goal here would be to replace Redis with an ETS instance and achieve a global cache for my elixir applications using ETS. Thus far I was not able to find any article detailing configurations for such, so I wonder:
- Is it possible to use ETS as a global cache via HTTP, the same way Redis is being using in the above example?
- If so how can I do it?
- If it is possible, is it worth the effort, or does the community advice I use Redis instead? (maybe because it is easier to setup, for example)
Where Next?

Trending in Questions



Other Trending Topics


Latest on Elixir Forum
Sponsor Spotlight

Producing high quality Elixir screencasts since 2017.
Categories:
Sub Categories:
Forums
Popular Tags
- #ecto
- #liveview
- #troubleshooting
- #learning-elixir
- #library
- #deployment
- #erlang
- #testing
- #genserver
- #mix
- #absinthe
- #remote-other
- #otp
- #plug
- #how-to-question
- #macros
- #postgres
- #elixirconf
- #channels
- #exunit
- #discussion
- #code-sync
- #podcasts
- #javascript
- #onsite
- #dialyzer
- #docker
- #authentication
- #umbrella
- #full-time-contract
- #podcasts-by-brainlid
- #ai
- #ecto-query
- #elixirconf-us
- #blog-post
- #elixir-ls
- #phoenix_html
- #iex
- #graphql
- #genstage
- #websockets
- #supervisor
- #advent-of-code
- #distillery
- #processes
- #elixirconf-eu
- #api
- #forms
- #metaprogramming
- #hex
Our Sponsors

Build Elixir applications with speed and confidence.

Supporting innovation across the BEAM ecosystem.

We build reliable cloud platforms for business-critical systems.

Catch errors, track performance, monitor hosts and more.

Elixir, Erlang & BEAM conferences from Code Sync - join us in 2026!

Practical resources that improve the lives of professional developers.

**Building the future of software with AI, trust, and human connection.**

The deployment platform built for Elixir: PaaS ease, VPS control.

The team behind Membrane, Popcorn, LiveDebugger. Available for hire.

Courses that'll move you from confusion to "Aha, now I get it!"
Showing Posts 1 to 10- Show Best Posts
- Show All (oldest first)
- Show All (newest first)
LostKobrakai
It’s possible. You could always build a http endpoint around ets and server http requests that way. But none of that comes “built in” and I doubt it’s worth it in the general case.
On the beam you also have mnesia which allows you to share kind of an ets table across the cluster, but it’s not quite straight forward to use. That’s local state synchronized across the cluster and not accessing one shared resource.
Without much detail on why you need a global cache I’d probably suggest staying with redis, lacking any reasonable means of doing a tradeoff with other options.
cevado
yes, for sure.
If machine A and machine B are both elixir machines, you could use either Cachex or Nebulex, both takes advantage of a cluster of machines to distribute ets tables across nodes
I particularly think that if you have an elixir application is more simple and less expensive clusterizing your nodes and use ets than use redis.
mpope
If you don’t want to bring an external dep in, the BEAM ships with Mnesia which sits ontop of ETS and adds a consistent distributed database.
However, when two nodes stop communicating due to a network fault Mnesia can be tricky to recover.
tangui
This is what
http_cache_store_diskandhttp_cache_store_memorydo whencluster_enabledis set totrue: they exchange cached responses by using distributed erlang and store them either in ETS table or on disk (and in this latter case, metadata is still stored in memory).They take into account that nodes can have different requirements such as available disk space or memory and therefore they handle cached response autonomously. A cached response can be discarded from one node and still be available on another.
If you want to cache HTTP responses from Phoenix / Plug, you can take a look at
plug_http_cache.dimitarvp
Is fetching a cached value from another node really worth it? Is it crushingly faster?
I have my doubts. Would love to see actual metrics.
Fl4m3Ph03n1x
So your hypothesis is that a global Redis instance will always be faster than a Cachex cluster, correct?
I am not sure how the cluster works, but if data is replicated in all the cluster machines, the speed should be faster, although you now have other problem to deal with, such as the split brain.
D4no0
What about running separate caches on both instances? You will waste a little bit more ram, however you will get rid of a lot of complexity, which IMO is perfect, as ram is dirt cheap these days.
dimitarvp
No, my hypothesis is that having a separate local cache for each node is going to work best. People really over-optimize for the wrong things I feel (and some of my practice has proven this hypothesis correct; accentuating the “some” here). Having 3 separate nodes doing a DB query cache each is honestly not a big deal at all, especially if the cached DB query cache should last at least 10 seconds; even in these conditions a local cache is more than enough.
To me the whole idea of “fetch cache from the network” is just hilarious in general, even though I’ve witnessed cases where it was still worth it (we’re talking results from SQL materialized views that were taking 10+ seconds to calculate; in all other cases however, distributed cache is just technology triumphing over itself, and over common sense as well).
tangui
No need to fetch from the network upon user request if each node has its own local cache, and preemptively fills its cache with data from other nodes The only role of a cache, after all, is to be full, and with the “hottest” objects (HTTP responses, …).
This is what
http_cache_store_*do when clustering is enabled: each node aggressively downloads HTTP response it doesn’t know to become full quicker and have the latest objects. Nodes also query1_000objects (by default) from other nodes at startup to warm up.dimitarvp
So how does that work exactly? At app startup one node warms up its cache and all other nodes download that warmed cache from it before they start?