
sorentwo
Hello!
tl;dr Announcing Oban, an Ecto based job processing library with a focus on reliability and historical observability.
After spending nearly a year building Kiq, an Elixir port of Sidekiq with most of the bells and whistles, I came to the realization that the model was all wrong. Most of us don’t want to rely on Redis for production data, and Sidekiq is a largely proprietary legacy system. Not the best base for a reliable job processing system.
So, I took the best parts of Kiq and some inspiration from EctoJob and put together Oban. The primary goals are reliability , consistency and observability. It is fundamentally different from other background job processing tools because it retains job data for historic metrics and inspection.
Here are some of the marquee features that differentiate it from other job processors that are out there (pulled straight from the README):
- Isolated Queues — Jobs are stored in a single table but are executed in distinct queues. Each queue runs in isolation, ensuring that a jobs in a single slow queue can’t back up other faster queues.
- Queue Control — Queues can be paused, resumed and scaled independently at runtime.
- Job Killing — Jobs can be killed in the middle of execution regardless of which node they are running on. This stops the job at once and flags it as
discarded. - Triggered execution — Database triggers ensure that jobs are dispatched as soon as they are inserted into the database.
- Scheduled Jobs — Jobs can be scheduled at any time in the future, down to the second.
- Job Safety — When a process crashes or the BEAM is terminated executing jobs aren’t lost—they are quickly recovered by other running nodes or immediately when the node is restarted.
- Historic Metrics — After a job is processed the row is not deleted. Instead, the job is retained in the database to provide metrics. This allows users to inspect historic jobs and to see aggregate data at the job, queue or argument level.
- Node Metrics — Every queue broadcasts metrics during runtime. These are used to monitor queue health across nodes.
- Queue Draining — Queue shutdown is delayed so that slow jobs can finish executing before shutdown.
- Telemetry Integration — Job life-cycle events are emitted via Telemetry integration. This enables simple logging, error reporting and health checkups without plug-ins.
Version v0.2.0 was released today. Please take a look at the README or the docs and let me know what you think!
https://github.com/sorentwo/oban
— Parker
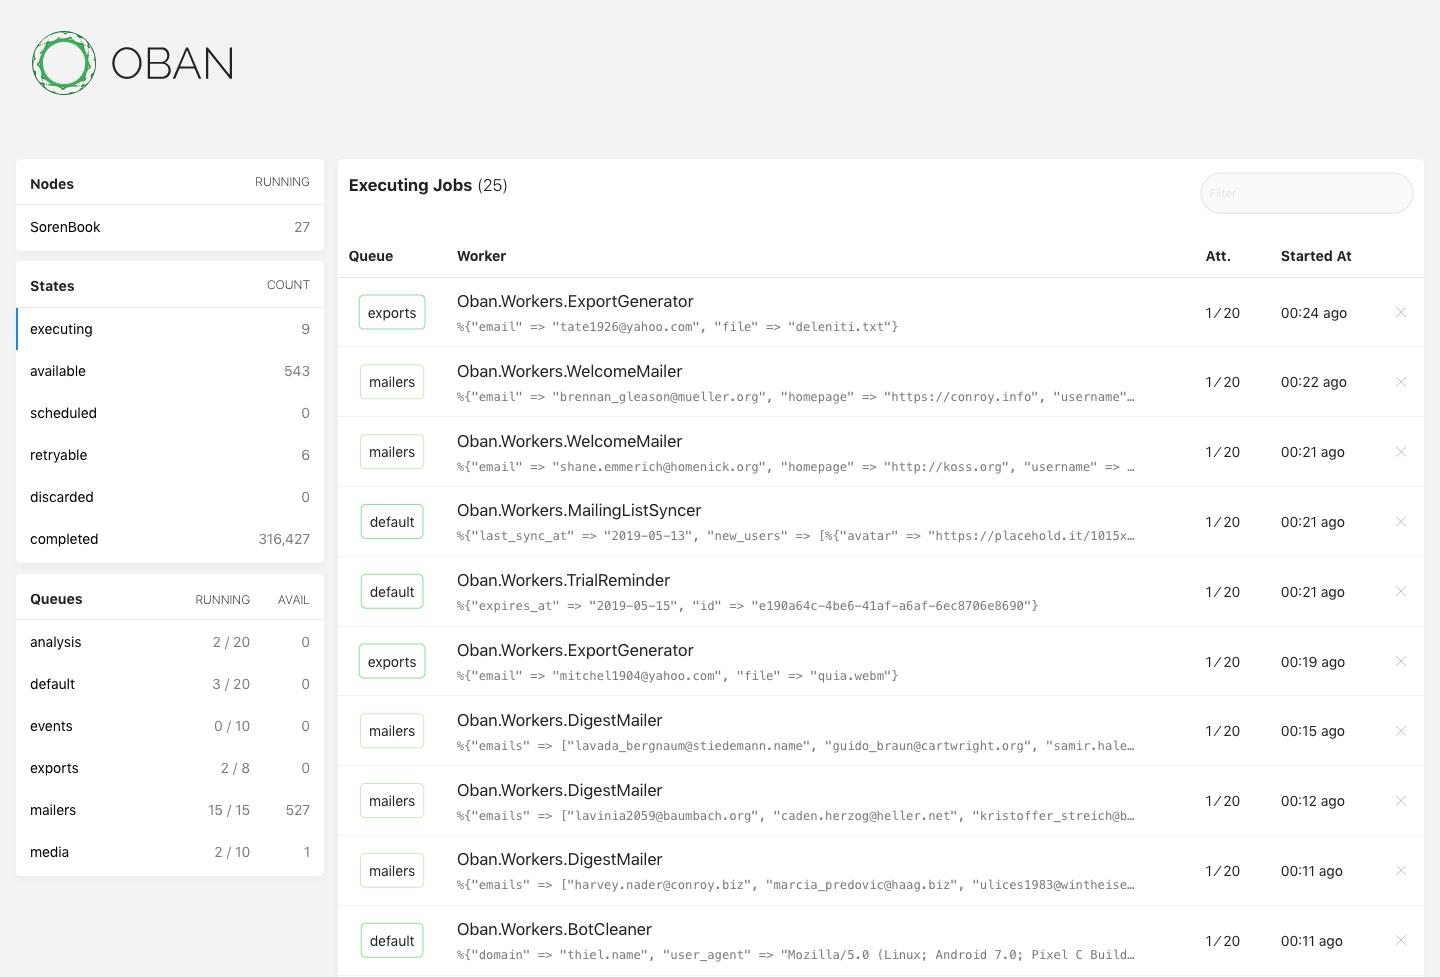
One more thing! A stand-alone dashboard built on Phoenix Live View is in the works.
The killer feature for any job processor is the UI. Every sizable app I know of relies on a web UI to introspect and manage jobs. It is very much a WIP, but here is a preview of the UI running in an environment with constant job generation:
Where Next?

Trending in Announcing





Other Trending Topics





 Latest Oban Threads
Latest on Elixir Forum
Sponsor Spotlight

Elixir, Erlang & messaging conferences from Code Sync. Next up: ElixirConf US (10–11 Sep) & Code BEAM Europe (21–22 Oct), Haarlem + online.
Categories:
Sub Categories:
Forums
Popular Tags
- #ecto
- #liveview
- #troubleshooting
- #learning-elixir
- #library
- #deployment
- #erlang
- #testing
- #genserver
- #mix
- #absinthe
- #remote-other
- #otp
- #plug
- #how-to-question
- #macros
- #postgres
- #elixirconf
- #channels
- #exunit
- #discussion
- #code-sync
- #podcasts
- #javascript
- #onsite
- #dialyzer
- #docker
- #authentication
- #umbrella
- #full-time-contract
- #podcasts-by-brainlid
- #ecto-query
- #ai
- #elixirconf-us
- #blog-post
- #elixir-ls
- #phoenix_html
- #iex
- #graphql
- #genstage
- #websockets
- #supervisor
- #advent-of-code
- #distillery
- #processes
- #api
- #forms
- #elixirconf-eu
- #metaprogramming
- #hex
Our Sponsors

Supporting innovation across the BEAM ecosystem.

We build reliable cloud platforms for business-critical systems.

Catch errors, track performance, monitor hosts and more.

Error tracking, logs, uptime, and Just Enough APM. Built for developers.
Elixir, Erlang & BEAM conferences from Code Sync - join us in 2026!

Practical resources that improve the lives of professional developers.

Producing high quality Elixir screencasts since 2017.

**Building the future of software with AI, trust, and human connection.**

The team behind Membrane, Popcorn, LiveDebugger. Available for hire.

Courses that'll move you from confusion to "Aha, now I get it!"
Showing Posts 131 to 140- Show Best Posts
- Show All (oldest first)
- Show All (newest first)
sorentwo
Oban v0.12.0 is out with some fun features, testing improvements, bug fixes and a helpful (optional) migration for large pruning operations. Thanks to all of the contributors who made this one possible!
From the CHANGELOG
Migration Optional (V7)
The queries used to prune by limit and age are written to utilize a single partial index for a huge performance boost on large tables. The new V7 migration will create the index for you—but that may not be ideal for tables with millions of completed or discarded jobs because it can’t be done concurrently.
If you have an extremely large jobs table you can add the index concurrently in a dedicated migration:
Added
[Oban] Add
start_queue/3andstop_queue/2for dynamically starting and stopping supervised queues across nodes.[Oban] Add
drain_queue/3to accept drain options.with_scheduled: trueallows draining scheduled jobs.[Oban] Expose
circuit_backoffas a “twiddly” option that controls how long tripped circuit breakers wait until re-opening.[Oban.Testing] Accept a value/delta tuple for testing timestamp fields. This allows more robust testing of timestamps such as
scheduled_at.[Oban.Telemetry] Emit
[:oban, :trip_circuit]and[:oban, :open_circuit]events for circuit breaker activity. Previously an error was logged when the circuit was tripped, but there wasn’t any way to monitor circuit breakers.Circuit breaker activity is logged by the default telemetry logger (both
:trip_circuitand:open_circuitevents).Fixed
[Oban.Query] Avoid using prepared statements for all unique queries. This forces Postgres to use a custom plan (which utilizes the compound index) rather than falling back to a generic plan.
[Oban.Job] Include all permitted fields when converting a Job to a map, preserving any optional values that were either specified by the user or came via Worker defaults.
[Oban.Migrations] Guard against missing migration modules in federated environments.
Changed
[Oban] Allow the multi
nameprovided toOban.insert/3,4to be any term, not just an atom.[Oban.Query] Use a consistent and more performant set of queries for pruning. Both pruning methods are optimized to utilize a single partial index.
brainlid
For people interested in Oban, Parker Selbert (@sorentwo) was recently on the ElixirMix podcast talking about it.
https://devchat.tv/elixir-mix/emx-079-oban-with-parker-selbert/
smaximov
I think you forgot to push a tag for v0.12.0 to Github.
sorentwo
Quite right. Pushed it up now.
jaimeiniesta
I’ve switched a production app to Oban, the change from Exq has been super smooth, and I’ve also been able to get rid of Quantum and Redis.
So far it’s been working for 48 hours and processed 150K jobs, zero problems
Thanks!
thousandsofthem
Well, Redis is about a lot of more load than that, then regular database becomes overloaded
sorentwo
Redis is excellent in many capacities but persistent storage isn’t one of them. When background jobs are doing work that is important to your business then you should treat them like the rest of your data.
You’d have to do a massive amount of background work to overload a production PG database. Redis is fast, but it is single threaded and when you do complex work on the server (e.g. with lua scripts) then it can get overloaded as well—a medium-traffic system I work on has 70k+ timeout errors from Redis over the past several months. Application level pooling doesn’t help much either because the server on the other end is still only single threaded.
sb8244
This one might be application specific. I am cautious about extracting meaning about Redis based on this. I do agree, though, that having persistence through Postgres for jobs is really useful and is one of the best parts of using PG for a job server. My application does about 10k+ inserts/job processes per second to Redis (through Sidekiq LUA scripts) at peak and I haven’t seen these timeouts before.
Application pooling is pretty significant with Redis, and I would say is almost required for production usage, because it parallelizes the network traffic with Redis. The work is still single-threaded, but the network time is significantly reduced. Here is an image that demonstrates the same amount of work in a singular vs pooled Redis environment. The pooling would have a significant impact here.
None of this has much to do with Oban, though. Postgres works great for 99% of applications, and could be tuned with something like Citus for extremely high throughput environments. Many people will choose not having another tool in their stack, so they’ll choose Oban.
sorentwo
Totally fair. That is definitely application specific and Redis is being used as the glue between a lot of things in that system (in addition to Sidekiq LUA and Kiq LUA scripts). I only meant to illustrate that Redis can have timeouts too when it gets enough load.
sb8244
Fair enough and a good thing to remember! I was very sad when my Redis bandwidth maxed out due to an application specific issue once.