
vegabook
adbc seems to use a huge amount more memory than “native” drivers.
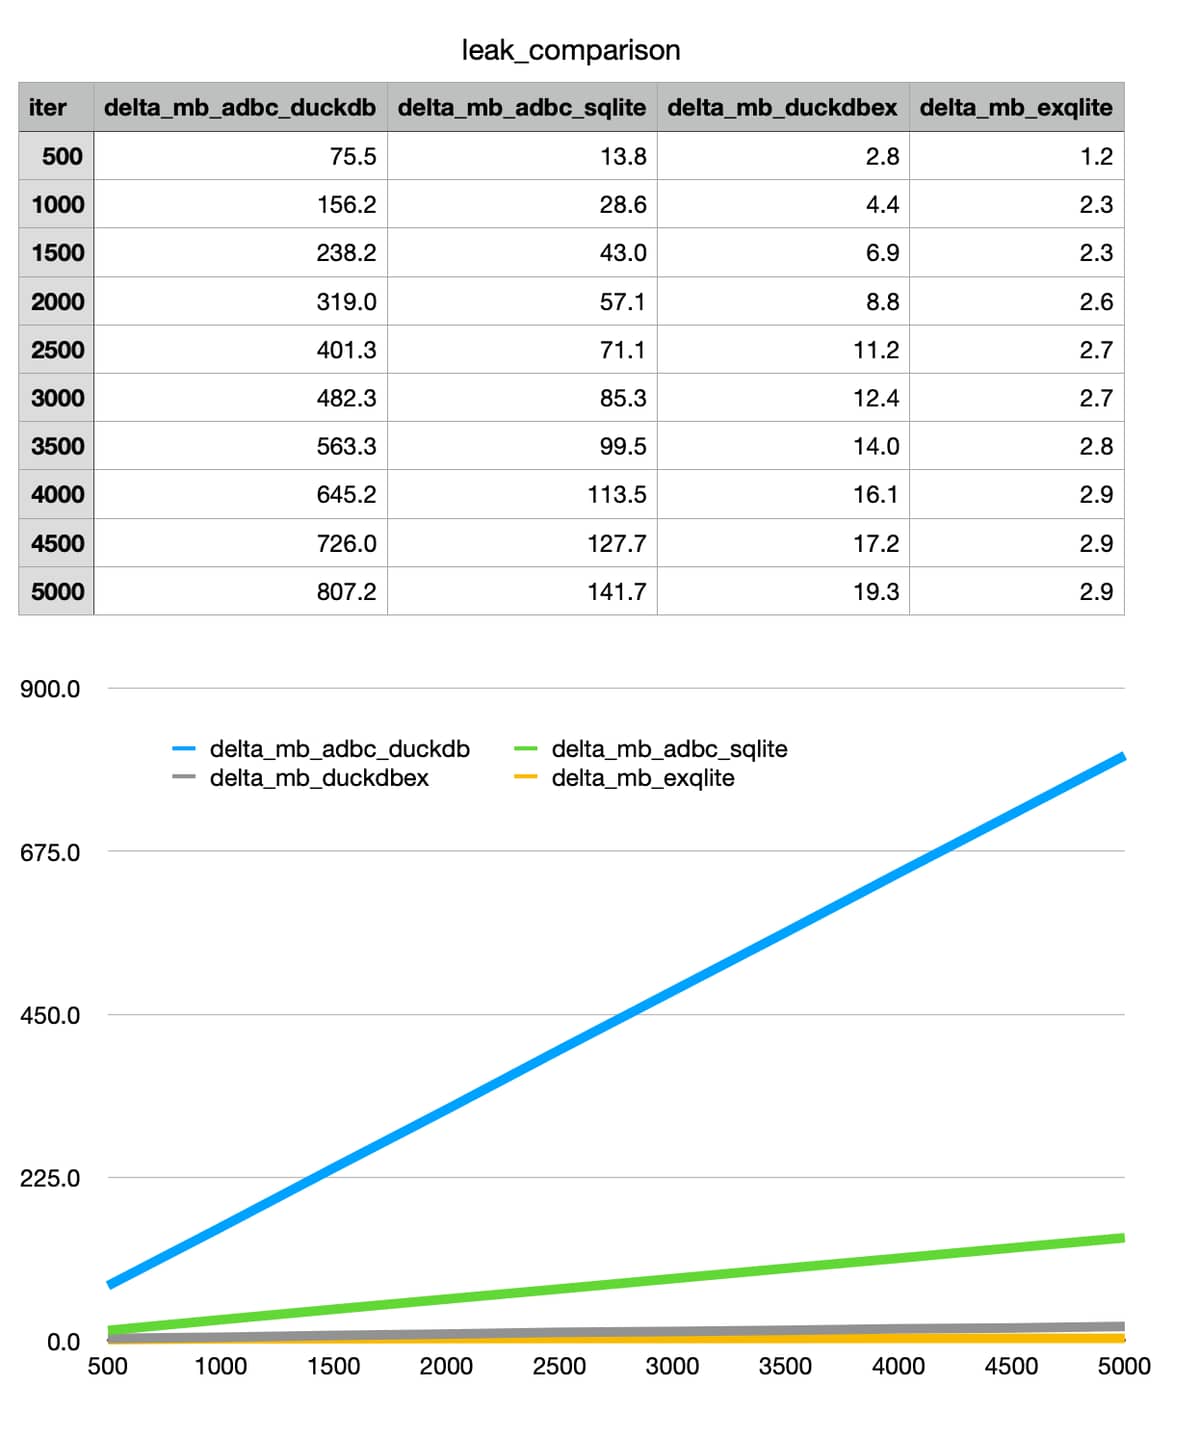
I’m dumping large amounts of data each minute, about 600k data points across 10k different identifiers. I need column store for querying so I have gone to duckdb via adbc. But it’s using tons of memory even though I am specifiying an on disk file. I have written a small test to show what I mean in this repo: GitHub - vegabook/adbc_leak_demo · GitHub . You’ll see that adbc basically accumulates memory, especially for duckdb, but also for sqlite, at a much higher pace than native drivers.
I’d like to stick to “offical” adbc if possible as it will also allow me more easily to swap out backends. So is this a bug or some implementation issue? What can I do to avoid this behaviour? As it stands it basically makes adbc difficult to use right now for append workflows as memory just keeps on growing forever. Even using sqlite backend the memory growth is kind of a concern. duckdbex is kind of acceptable as memory growth seems slow enough that a once-every-few-hours restart or something should keep thins manageable. But really only exqlite currently is fit for a long-running ingest, but it has the major downside of not doing column store so data science queries will be ultra slow.
Any advice on how to solve the “lots of fast ingest, must be column store, mustn’t leak memory” problem?
The table and chart show process memory growth as rows get ingested. Each iter is 100 rows. All are on-disk workflows so apart from a bit of buffer delta early on, you’d expect stability.
Where Next?

Trending in Questions



Other Trending Topics





Latest on Elixir Forum
Sponsor Spotlight

Producing high quality Elixir screencasts since 2017.
Categories:
Sub Categories:
Forums
Popular Tags
- #ecto
- #liveview
- #troubleshooting
- #learning-elixir
- #library
- #deployment
- #erlang
- #testing
- #genserver
- #mix
- #absinthe
- #remote-other
- #otp
- #plug
- #how-to-question
- #macros
- #postgres
- #elixirconf
- #channels
- #exunit
- #discussion
- #code-sync
- #podcasts
- #javascript
- #onsite
- #dialyzer
- #docker
- #authentication
- #ai
- #umbrella
- #full-time-contract
- #podcasts-by-brainlid
- #ecto-query
- #blog-post
- #elixirconf-us
- #elixir-ls
- #phoenix_html
- #iex
- #graphql
- #genstage
- #websockets
- #supervisor
- #advent-of-code
- #distillery
- #processes
- #elixirconf-eu
- #api
- #forms
- #security
- #hex
Our Sponsors

Build Elixir applications with speed and confidence.

Supporting innovation across the BEAM ecosystem.

Catch errors, track performance, monitor hosts and more.

Error tracking, logs, uptime, and Just Enough APM. Built for developers.

Elixir, Erlang & BEAM conferences from Code Sync - join us in 2026!

Practical resources that improve the lives of professional developers.

Bringing learning, work and compliance together since 1987.

**Building the future of software with AI, trust, and human connection.**

The team behind Membrane, Popcorn, LiveDebugger. Available for hire.

Courses that'll move you from confusion to "Aha, now I get it!"